统计大讲堂第314讲:数据增强型预测框架:生成兼顾可控公平性-忠实度权衡的公平合成标签
2026-09-24
A data-augmented predictive framework for generating fair synthetic labels with controlled fairness-faithfulness trade-offs
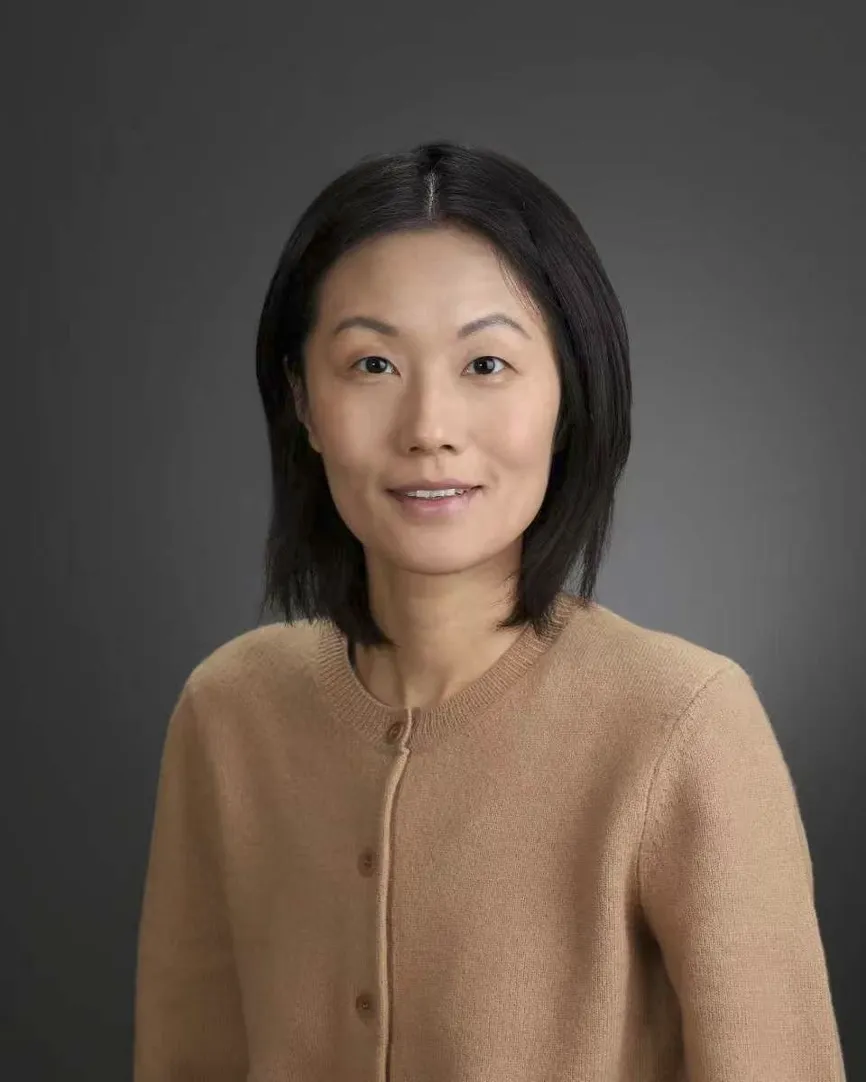
主讲人:Bei Jiang
Dr. Bei Jiang is a full Professor in the Department of Mathematical and Statistical Sciences at the University of Alberta, a Canada CIFAR AI Chair, and a Fellow of the Alberta Machine Intelligence Institute (Amii). Her research focuses on the statistical foundations of trustworthy AI, including data privacy, algorithmic fairness, uncertainty quantification, federated learning, and statistical learning for complex and heterogeneous data. She has published extensively in leading statistics and machine learning venues, including the Journal of the American Statistical Association, Annals of Statistics, Journal of Machine Learning Research, NeurIPS, ICML, and ICLR. Dr. Jiang currently serves as Co-Editor of Statistics Surveys, Associate Editor for the Journal of the American Statistical Association, and Area Chair for NeurIPS 2026. She is a recipient of the 2025 COPSS Emerging Leader Award and the University of Alberta Faculty of Science Research Award.
1 报告信息
时间
2026年9月29日(周二)16:00
地点
中国人民大学中关村校区明德主楼1016会议室
2 报告摘要
Algorithmic decision systems are increasingly used in socially sensitive domains, raising concerns about bias inherited from historical data. Fair synthetic data generation provides a pre-processing strategy for bias mitigation, but existing methods often rely on black-box generative models whose tuning parameters have limited theoretical interpretation. We propose fDA, a Data-Augmented predictive framework for generating Fair synthetic labels. The framework combines a fairness-enforcing model, which specifies a fair reference conditional law satisfying the desired fairness constraint, with a faithfulness-preserving model, which generates auxiliary variables from observed labels to retain controlled original-label information. Synthetic labels are sampled from the predictive distribution induced by jointly modeling these components, coupled with a tuning mechanism. For continuous labels, the Gaussian working specification yields explicit calibration of the effective noise level to a target population upper bound on unfairness. For both continuous and ordinal labels, the predictive distribution is fully specified for each tuning value, enabling empirical calibration of the achieved fairness--faithfulness trade-off. Theoretically, when the auxiliary variable becomes fully informative, synthetic labels converge to the original labels in probability and distribution; when it becomes non-informative, the mechanism reduces to the fair reference law. Experiments on simulated and real datasets show interpretable trade-offs and improved faithfulness over GAN-based baselines.